Online recommendations work better when algorithms learn why viewers turn away
Encoding explicit viewer explanations into mathematical representations allows content engines to generalize negative reactions across millions of livestreams without relying purely on clicks.
A person watching a digital broadcast may close the application for reasons an automated system cannot easily deduce. Someone might click away because a host speaks with an affected cadence, because a stunt feels irresponsible, or simply because dinner is ready. To the computer program monitoring the session, each of these departures registers as the same silent interruption: a timestamped skip and a drop in elapsed watch time.
Recommendation platforms have historically treated user attention as a sequence of implicit clues.1 The software tracks clicks, views, scroll speeds, and explicit dismissals, assembling these actions into statistical profiles that predict which item a viewer is likely to tap next.1 Yet these behavioral breadcrumbs capture what someone did rather than why they chose to do it.1 A single recorded swipe can stem from disgust, boredom, accidental contact with the glass screen, or external distraction. Because the observed behavior fails to specify which particular quality alienated or charmed the viewer, mathematical models often struggle to generalize preference rules from actions alone.1
A study posted on the preprint server arXiv by Haoke Xiao and colleagues at Kuaishou Technology describes an architecture designed to collect and integrate direct natural-language explanations into an industrial content engine.1 The researchers introduced a system named SARA, an acronym for Scaling Articulated Rationales, deployed across the Kuaishou Live ecosystem.1 By soliciting concise statements from viewers and processing them through artificial intelligence models, the framework attempts to transform rare personal opinions into mathematical signals that guide algorithmic ranking across millions of active broadcasts.
Why do traditional algorithms struggle to interpret viewer choices?
Modern content engines fail to grasp underlying motivations because behavioral data lacks semantic precision.1 An automated model can detect that an account holder skipped three cooking broadcasts in a row, but the program cannot determine whether the viewer disliked the recipes, found the audio grating, or objected to the lighting. The engineering response to this limitation has involved ingesting multimodal data, including video frames, speech transcripts, topic hashtags, and audience text comments.1 These inputs supply richer descriptions of what appears on screen, yet they still do not reveal which specific detail drove an individual preference decision.1
Direct explanations from users solve this ambiguity, but they introduce a severe data distribution challenge. In ordinary consumer software, viewer explanations are vanishingly scarce. The paper notes that explicit articulations of why a person likes or dislikes an item occur in fewer than 1% of total consumption events, because the natural impulse of an audience member is simply to navigate away.1 Furthermore, when users do provide commentary through application forms, the text is typically fragmented, colloquial, and prone to extreme emotional distortions, rendering raw submissions difficult to feed directly into numerical ranking models.
Teaching language models to invent these explanations has proved equally brittle. When general-purpose multimodal models are asked to infer why a viewer departed, the models observe only the outcome and often fabricate plausible rationalizations that fail to reflect the actual motives of real people.1 The authors observed that bridging this gap requires gathering authentic user explanations, verifying their factual relevance against the video footage, and converting isolated sentences into structured preference tags.1
How can an automated platform collect reliable feedback from millions of users?
The platform collects user motives by triggering interactive two-step questionnaires inside live broadcasts under strictly timed conditions.1 In the first step, a prompt asks the viewer to declare an overall preference choice, selecting either positive or negative polarity.1 If the user marks positive, the software displays an open-ended inquiry asking what the viewer likes most about the host; if the user selects negative, the application asks why they do not wish to continue watching.1 This two-tier prompt ensures that every submitted statement is anchored to an unambiguous positive or negative polarity.
To prevent arbitrary submissions while keeping audience retention high, Xiao and colleagues introduced a delayed triggering mechanism calibrated to 10 seconds. The authors determined that if the survey arrives too quickly, viewers have not formed a stable assessment of the broadcast, whereas if the delay extends too long, dissatisfied users close the video before the system can ask for their opinion.1 The 10-second delay functions as an engineering compromise between response quality and audience coverage.
The system also regulates distribution through a sparse questionnaire delivery formula that adjusts display probability to avoid audience fatigue.1 Delivery probability ranges between 1% and 20%, maintaining an initial baseline of 5% and adjusting dynamically according to response rates measured across five-minute sliding windows. When audience responsiveness drops below a target threshold of 12%, delivery probability scales down to prevent annoyance.1 To encourage constructive responses, a lightweight model evaluates incoming text in real time across six criteria, granting a small virtual currency reward in KuaiCoin if the response scores above two on a four-point scale.
During an active observation window spanning 185 days between February 12 and August 30, 2026, the collection engine harvested 1,915,718 candidate statements, averaging roughly 10,400 responses per day.1 The raw texts then passed to an offline evaluation module containing six specialized algorithmic judges.1 These evaluators measured coherence, relevance, specificity, safety, polarity consistency, and grounding against the live video and transcript.1 Out of the roughly 1.92 million candidates, the filtering pipeline retained 187,532 high-quality rationales, representing an offline yield of 9.8%.1
How do individual statements become broad recommendation signals?
Individual statements become broad recommendation signals by aggregating verified comments into author-level profiles and training a language model to infer similar properties for broadcasters (which may not have been peer reviewed).1 The raw collection matrix connected 141,461 individual respondents to 86,564 broadcast authors, with each contributing user submitting an average of approximately 1.33 questionnaires.1 Because single users rarely contributed enough text to construct comprehensive individual preference profiles, the researchers inverted the relationship, grouping submitted rationales around the authors being watched, who averaged roughly 2.17 responses each.1
Analysis of the retained text revealed that 82% of individual questionnaire responses contained no more than 10 Chinese characters.1 Despite their extreme brevity, these snippets contained self-contained preference factors, describing concrete traits such as an unusual makeup style, loud promotional shouting, or food performances that appeared deceptive. The researchers normalized these colloquial phrases into atomic semantic tags, assembling a curated dataset designated as SARA-HQ.
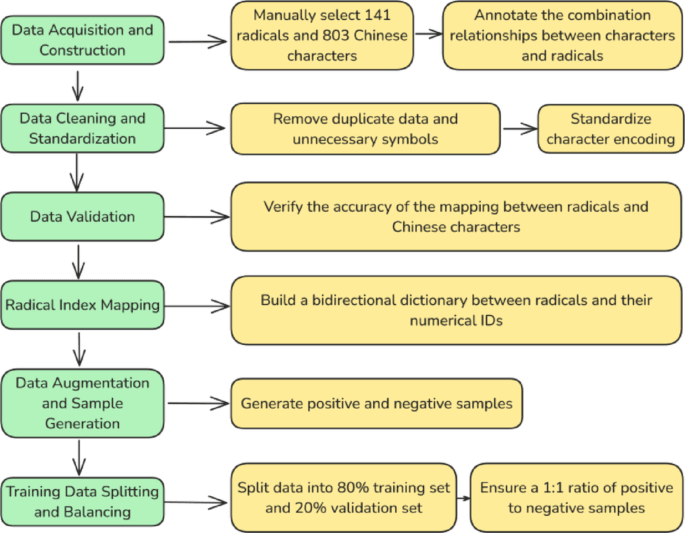
Xiao and colleagues then adapted an open multimodal language model into a dedicated generator called SARA-7B.1 The model underwent supervised fine-tuning followed by quality-refining direct preference optimization, learning to ingest video frames, speech transcripts, and audience comments to predict positive and negative preference tags. While the verified human questionnaire dataset covered 86,564 broadcast authors, deploying SARA-7B allowed the system to synthesize grounded rationales across the platform catalogue of 10 million authors.1
These synthesized reasons are fed into the production ranking model, named SARA-Ranker, using two distinct operational branches.1 One branch handles positive preference matching by comparing a user historical viewing trajectory with the positive rationales attached to incoming candidate broadcasts.1 The second branch performs rejection-memory modeling, which generalizes negative feedback across semantically connected broadcasts.1 If an account holder expresses distaste for dangerous riding stunts, the ranking model suppresses similar content across other channels even if the viewer has never encountered those specific broadcasters.
What are the limits of relying on generated user rationales?
The findings presented in the study represent an industrial system deployment and offline evaluation rather than a laboratory proof of universal preference modeling.1 The reported gains reflect performance on a single live-streaming mobile platform operating primarily in the Chinese language, where user interactions and comment norms follow specific cultural conventions. Because the paper is an engineering preprint that has not yet completed formal peer review, its claims about ranking improvements have not been independently audited by outside computer scientists.1
Furthermore, the generated signals depend heavily on the assumption that an artificial intelligence model can accurately reproduce authentic human reasoning from visual and acoustic context. Although the authors applied multi-stage filtering and preference optimization, automated generators inherently carry the risk of assigning plausible explanations to videos where real audience motivations differ. A model may fixate on salient visual elements, such as rural courtyard settings or pyrotechnic displays, while missing subtler social dynamics that alienate live viewers.
The physical delivery of questionnaires also introduces potential sampling distortions that numerical adjustments cannot entirely erase. Even with dynamic probability controls and micro-rewards, individuals who choose to type explanations into a smartphone interface represent an active minority of the platform user base. The 9.8% offline curation yield illustrates that more than nine out of 10 collected responses failed basic standards of coherence, safety, relevance, or grounding.1 The system relies on filtering algorithms to discard low-quality submissions, meaning that any systemic blind spots in the automated judges will inevitably shape the downstream preference tags.
What changes when algorithms know why people leave?
Teaching recommendation systems to process causal explanations changes how platforms diagnose negative interactions. Historically, negative behavioral signals have presented an asymmetric challenge for software architects. When an audience member watches a broadcast for 40 minutes, the algorithm receives strong confirmation of interest. But when an audience member leaves after 15 seconds, the software cannot tell whether the user was repelled by the topic, disliked the personality on screen, or simply stepped away from their desk.
By transforming sparse feedback into generalized semantic profiles, recommendation engines can separate incidental departures from fundamental content rejections. Platforms can avoid repeatedly testing unwanted themes on sensitive users, reducing audience frustration while preserving exposure for diverse creators. As large language models grow more adept at video and audio comprehension, the technical bottleneck in digital curation is shifting from detecting user actions to understanding human motivation.
What this rests on
34 sentences trace to 1 source.
-
1
HX
Haoke Xiao, Yueyang Liu, Yuhui Zhang, Xiang Chen, Yufei Liu, Jia Xu, Yalong Guan, Xiaolan Zhu, Xiaoyu Zhang, Shijun Wang, Shuang Yang, Zijie Meng, Zejian Zhang, Ruochen Yang, Xiangyu Wu, Tingting Gao, Paper · arxiv.org · 17 Sep 2026 Scaling Articulated Rationales for MLLM-based Recommendation Preprint · may not have been peer reviewed See the source